Stop GPU OOMs.
Turn burst traffic into an orderly line.
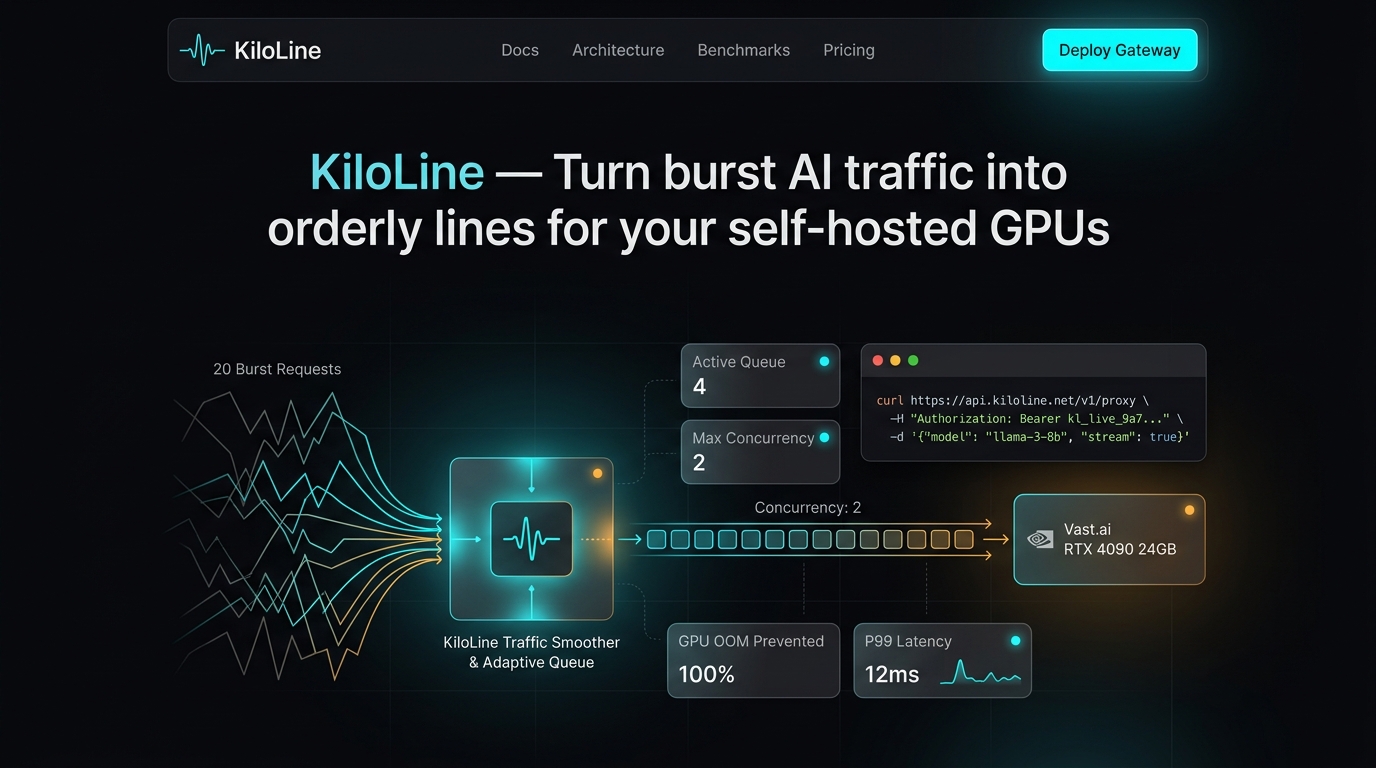
Renting budget 4090s on Vast.ai or RunPod for ComfyUI and TTS? A sudden wave of 10 concurrent users will crash your GPU with CUDA Out-Of-Memory errors. KiloLine buffers the burst at the edge and serializes requests safely to match your hardware capacity.
Traffic Smoothing Simulation
Simulate 10 concurrent inference calls hitting a single RTX 4090 (24GB VRAM) instance.
Realtime Gateway Intelligence
Monitor incoming burst queues, live worker slots, and spot failover states from a single developer dashboard.
THE SELF-HOSTED GPU DILEMMA
Why bare-metal GPUs fail when traffic strikes
You don't need expensive enterprise clusters. You just need an intelligent traffic buffer.
- Instant CUDA OOM: 10 users requesting image generation at the same second overwhelms 24GB VRAM and kills the process.
- Gateway 504 Timeouts: Frontends drop connections when generation takes 25s without active streaming.
- Vulnerable to Scrapers: No built-in rate-limiting or anti-abuse protection on your direct IP.
- Zero Failover: If your spot instance gets interrupted, users are met with a completely dead API.
- Strict Concurrency Throttling: Set
max_concurrency: 2. KiloLine queues the remaining 8 requests cleanly in memory. - SSE Streaming & Webhooks: Maintains keep-alive state streams to your frontend until the media is ready.
- Edge Token Rate Limiting: Shield your backend GPU from DDoS, scrapers, and rogue loops.
- Automatic Spot Failover: Route instantly to a secondary standby node if the primary spot machine reboots.
SYSTEM BLUEPRINT
How the KiloLine pipeline operates
Minimal edge overhead, persistent durability, and zero-configuration client proxying.
Edge Ingestion
Global Hono Edge runtime captures incoming requests within 10ms. Validates API keys and payload sanity immediately.
Zero-Drop Queue
Excess requests over your capacity limit are instantly routed into a high-throughput persistent queue buffer.
Serialized Dispatch
The gateway leases requests strictly according to your configured concurrency slot (e.g., 2 parallel calls max to your Vast.ai 4090).
Stream & Callback
Long-running inferences stream generation progress via SSE or send signed Webhooks upon payload completion.
Just switch the Base URL
No massive SDK dependencies. Works with vanilla fetch, curl, or any HTTP client.
# Replace your raw GPU direct endpoint with KiloLine Gateway
curl -X POST "https://gateway.kiloline.net/v1/proxy" \
  -H "Authorization: Bearer kl_live_9f81a7b..." \
  -H "X-Target-Host: https://instance-4090.vast.ai:8000" \
  -H "X-Concurrency-Slot: 2" \
  -H "Content-Type: application/json" \
  -d '{
    "prompt": "Cyberpunk high-speed data pipeline, 8k octane render",
    "steps": 25
  }'
ENGINEERED FOR BUILDERS
Built for developers who value performance & budget
Dynamic Concurrency Cap
Dynamically regulate parallel workers per endpoint. Set ComfyUI to 1 slot and lightweight TTS to 4 slots with zero downtime.
Zero Cold Start
Unlike cloud container platforms that take 45 seconds to fetch weights on every cold boot, your rented GPU remains warm and ready.
Auto-Failover Mesh
Add primary and backup GPU hosts. If an active Vast.ai spot instance drops, incoming requests automatically route to your fallback instance.
SSE Streaming Keep-Alive
Stream percentage updates, interim steps, or queue wait times back to users without encountering 504 Gateway Timeout errors.
Zero Payload Storage
We never store your prompts, embeddings, or generated media. Traffic flows strictly through in-memory edge pipes directly to your instances.
IP & Token Shield
Keep your raw GPU IP hidden from public DNS. Enforce per-minute rate-limits and token budgets to prevent costly runaway bills.
GPU Cost Comparison Calculator
Calculate your monthly bill: Serverless GPU providers vs. Vast.ai + KiloLine gateway.
Serverless platforms charge by the second. As your user base expands, your bill scales linearly. With dedicated Vast.ai GPUs protected by KiloLine queue, your compute cost is flat—no matter how many users queue up.
Reclaim budget to train models or grow your product.
Frequently Asked Technical Questions
How much latency does KiloLine introduce to my requests?
KiloLine runs on lightweight Edge Runtime workers deployed across 30+ global locations. Edge routing and token verification add less than 8ms - 15ms of latency. For AI workloads that take 2s to 15s to complete, this overhead is negligible.
What happens if my Vast.ai spot instance gets terminated?
You can configure a primary host and a standby host. When KiloLine encounters continuous healthcheck failures or connection timeouts on the primary, it automatically pauses dispatching, trips the circuit breaker, and redirects pending queued requests to your standby host.
Do you store my user prompts or generated images?
No. We strictly abide by our Zero-Payload policy. KiloLine acts as a pass-through reverse proxy. Only telemetry metadata (timestamps, response status codes, execution duration, and queue depth) are recorded for analytics.
How is KiloLine different from self-hosting Celery or Redis Queue?
Self-hosting Celery requires provisioning a separate VPS, configuring Redis, handling SSL cert renewals, writing custom retry and backoff logic, and setting up SSE stream bridging. KiloLine provides this out-of-the-box in under 60 seconds.